Speaker
Ginger Holt, Senior Staff Data Scientist, Databricks
Moderator
Dr. Will Wei Sun, Associate Professor, Purdue University
Abstract
As AI systems shift from single-shot predictors to multi-step agents, evaluation must evolve from simple accuracy scores to statistically grounded assessments of behavior, reliability, and safety. This talk focuses on the statistics of LLM-based “judges” and multi-metric evaluation pipelines for trustworthy AI agents, drawing on large-scale experiments and tooling built around MLflow and Databricks Mosaic AI. We show how LLM judges are calibrated against human raters using percent agreement and Cohen’s kappa, with confidence intervals computed over diverse academic and proprietary datasets to quantify judgment reliability and avoid over-trusting noisy auto-metrics.
Building on this, we describe a principled evaluation stack that simultaneously measures quality, cost, and latency at both row and run levels, aggregating metrics such as answer correctness, guideline adherence, token counts, and end-to-end latency into statistically interpretable summaries for each experiment. We discuss how scorers and LLM judges are reused consistently from offline testing to online monitoring, enabling hypothesis-driven iteration and drift detection in production.
Finally, we connect these judge-level statistics to broader benchmark design, highlighting recent work on calibrating large benchmark suites (the Mosaic Evaluation Gauntlet) by requiring metrics to exhibit monotonic relationships with model scale, thereby filtering out “noisy” benchmarks that fail basic statistical sanity checks. The talk closes with open problems around uncertainty quantification for judge scores, multiple-testing corrections across large metric suites, and how hybrid models like promptable reward models can unify judgment and reward estimation in a single statistically analyzable framework.
About the Speaker
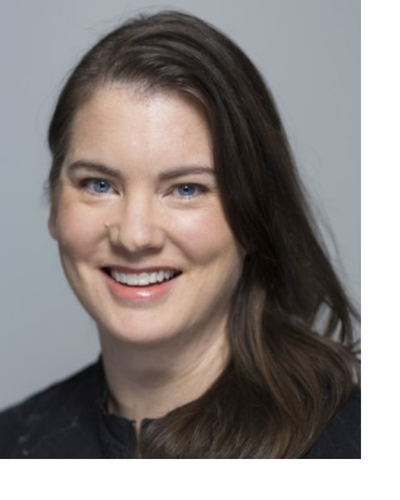 Ginger Holt is a Senior Staff Data Scientist at Databricks. She is a Leader with extensive industry and academic experience in cutting-edge statistical techniques for forecasting, experimentation, predictive modeling, causal inference, and machine learning, to enable data-driven, strategic, cost effective business decisions. Experienced developer of scalable, generalizable frameworks, tooling, and solutions with unified methodologies. Developer of robust solutions that balance practicality, explainability, and accuracy. Keen interest in effective communication of findings and partnering with business stakeholders for optimal implementation. Effective at leading cross-functional teams to frame ambiguous problems, collect and manage data efficiently, construct analytical models, build operational systems, and provide insights and recommendations to stakeholders.
About the Moderator
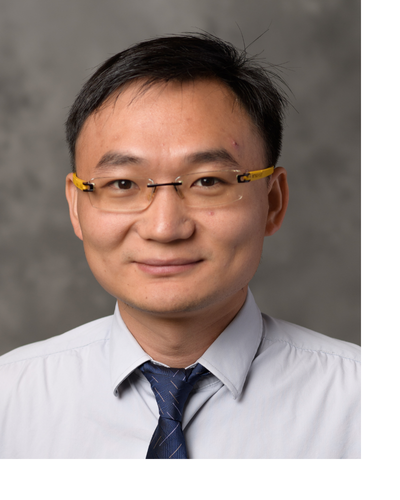 Dr. Will Wei Sun is an Associate Professor of Quantitative Methods at Purdue University's Mitchell E. Daniels, Jr. School of Business, with a courtesy appointment in the Department of Statistics. He serves as the PhD Coordinator for Quantitative Methods and is recognized for his expertise in statistical foundations of large language models, trustworthy reinforcement learning, tensor data analysis. Dr. Sun's research has been supported by notable grants from the National Science Foundation and the Office of Naval Research. Dr. Sun earned his Ph.D. in Statistics from Purdue University in 2015. Before that, he was a research scientist at Yahoo Labs and an assistant professor at Miami Business School. Dr. Sun is on the editorial board for Annals of Applied Statistics, Statistical Analysis and Data Mining. See Profile
Event Disclaimer
The views and opinions expressed by the speakers during this event are their own and do not necessarily reflect the views, positions, or policies of their employers, affiliated organizations, or any other entity. The speakers are participating in a personal capacity, and their statements should not be attributed to their respective companies or institutions.
About AI, StAtIstics and Data Science in Practice
The NISS AI, Statistics and Data Science in Practice is a monthly event series will bring together leading experts from industry and academia to discuss the latest advances and practical applications in AI, data science, and statistics. Each session will feature a keynote presentation on cutting-edge topics, where attendees can engage with speakers on the challenges and opportunities in applying these technologies in real-world scenarios. This series is intended for professionals, researchers, and students interested in the intersection of AI, data science, and statistics, offering insights into how these fields are shaping various industries. The series is designed to provide participants with exposure to and understanding of how modern data analytic methods are being applied in real-world scenarios across various industries, offering both theoretical insights, practical examples, and discussion of issues.
During Fall 2026, from September through December 2026, the series will focus on Trustworthy AI and the statistical, methodological, and governance foundations needed to develop, evaluate, and deploy AI systems responsibly and effectively. As AI becomes increasingly embedded in scientific research, business operations, public services, and societal decision-making, establishing confidence in the reliability, fairness, transparency, and accountability of these systems is essential. The series will examine approaches to measuring and mitigating bias, quantifying uncertainty and risk, evaluating robustness under changing conditions, and developing interpretable models and transparent evaluation frameworks that support informed decision-making. Emphasis will be placed on reproducibility, responsible data practices, privacy and security considerations, human oversight, and lifecycle monitoring to ensure that AI systems continue to perform as intended after deployment. By grounding discussions of AI development and governance in sound statistical reasoning and rigorous empirical evaluation, the series aims to promote AI systems that are not only accurate and innovative, but also trustworthy, equitable, and aligned with societal values.
See full list of featured topics (also below)
Featured Topics:
- Veridical Data Science - Speaker: Bin Yu, October 15,2024
- Random Forests: Why they Work and Why that’s a Problem - Speaker: Lucas Mentch, November 19, 2024
- Causal AI in Business Practices - Speakers: Victor Lo, and Victor Chen, January 24, 2025
- Large Language Models: Transforming AI Architectures and Operational Paradigms - Speaker: Frank Wei, February 18, 2025
- Machine Learning for Airborne Biological Hazard Detection - Speaker: Jared Schuetter, March 11, 2025
- Trustworthy AI in Weather, Climate, and Coastal Oceanography - Speaker: Dr. Amy McGovern, May 13, 2025
- Sequential Causal Inference in Experimental or Observational Settings - Speaker: Aaditya Ramdas, August 26, 2025
- Covariate Adjustment, Intro to Resampling, and Surprises - Speaker: Tim Hesterberg, October 3, 2025
- Bayesian Geospatial Approaches for Prediction of Opioid Overdose Deaths Utilizing the Real-Time Urine Drug Test - Speaker: Joanne Kim, November 18, 2025
- COVID-19 Focused Cost-benefit Analysis of Public Health Emergency Preparedness and Crisis Response Programs - Speaker: Nancy McMillan, December 11, 2025
- LabOS: The AI-XR Co-Scientist That Reasons, Sees and Works With Humans - Speaker: Mengdi Wang, January 20, 2026
- From LLMs to World Foundation Models & Robotics: The Next Frontier of Artificial Intelligence - Speaker: Robert Clark, February 24, 2026
- Recent Advances in the Statistical Foundations of Large Language Models - Speaker: Weijie Su, March 17, 2026
- Evaluating LLMs by Human Preference Using Arena AI - Speaker: Anastasios N Angelopoulos, April 17, 2026
- Causal Generalist Medical AI - Speaker: Hongtu Zhu, May 19, 2026
- Measuring Functional Wellbeing in Large Language Models - Speakers: Wenyu Zhang & Richard Ren, June 16, 2026
- Judging the Judges: Statistical Evaluation of LLM-Based Metrics for Trustworthy AI Agents - Speaker: Ginger Holt, September 15, 2026
- NISS Ai, Statistics & Data Science Webinar: Steve Sain, Jupiter Intelligence - Speaker: Steve Sain, October 20, 2026
- AI Advancing Business for ROIs, Outcomes, and Impact - Speaker: Kelly Zou, November 20, 2026
Event Type
- NISS Hosted
Cost
Website
Location
Policy